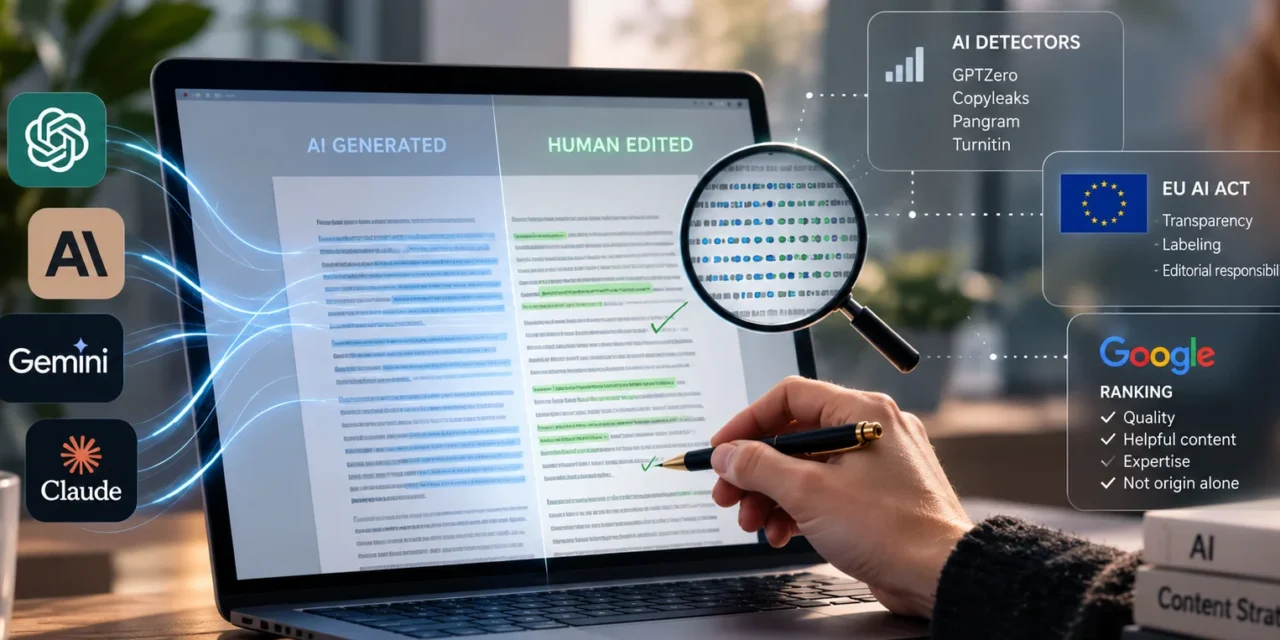
A text is created with the help of AI. An editor checks the figures, removes generic statements, adds her own experience and publishes it. The result is an article for which she takes responsibility. But can anyone still tell which sentences came from AI and which from her? And if so, does that affect how the page performs on Google?
These questions are relevant to anyone using AI in content creation. The answers quickly become confusing, however, because three different things are often mixed up. Some AI providers embed a watermark during text generation. AI detectors, by contrast, evaluate a finished text based on its language. Google, meanwhile, evaluates the published page. These may initially sound like three ways of identifying AI-generated text, but each method answers a different question.
The reason for taking a closer look comes from Anthropic. On August 14, 2026, the company announced that future Claude models would include a text watermark. This could make it possible to check whether Claude was involved in writing certain texts. How reliable such a check would be, however, depends on the text and how it has been edited. And even if Claude’s involvement can be demonstrated, that still tells us nothing about what Google thinks of the published article.
Watermarks and Detectors Look for Different Things
A text watermark is created during generation. A language model decides step by step which token comes next. Where several alternatives fit well, a method can use a key to influence the selection so that a statistical pattern emerges across many decisions. Readers see no additional characters. Anyone who has the key and the appropriate verification method can later examine whether the text matches this pattern.
The foundational research by Kirchenbauer and colleagues describes one possible method using groups of preferred tokens. Google DeepMind’s study on SynthID Text describes another approach adapted to the model’s output. Anthropic explicitly states that its method is a variant of SynthID Text. The basic principle is similar in all these approaches: a statistically detectable signal is embedded in the generated text. How this signal is technically embedded, however, differs considerably.
A general-purpose AI detector works differently. GPTZero, Copyleaks, Pangram or Turnitin receive a finished text and do not know the secret key of the model that generated it. They compare the text with patterns learned from human-written and AI-generated examples. One possible characteristic is the predictability of word choice. If one word is particularly often followed by exactly the same next word, some detection methods may consider the text more likely to have been machine-generated. But this is only one indicator among several. After all, humans can also write in a very uniform style, while AI-generated text can contain surprising expressions.
Both approaches share one limitation: they have to infer a text’s history from the available material. A watermark looks for a deliberately embedded signal and can therefore provide more convincing evidence under suitable conditions. A general-purpose detector can also evaluate texts from other models, but its assessment depends heavily on the training material, the language and any subsequent editing. A negative result from either method is not a certificate of authenticity. Conversely, a positive result is not definitive proof either. A detected watermark may indicate the involvement of a particular model, but it says nothing about how much a human subsequently changed.
What Claude, Gemini and ChatGPT Actually Mark
Anthropic describes its Claude watermark as a signal for future models. Older model versions are expected to be updated during a transition period. According to Anthropic, the corresponding detection capability is initially being offered through an API in a private preview for eligible organizations. Anyone hoping to paste an arbitrary text into a freely accessible portal will therefore not find a general official Claude checker. Even a positive result would only suggest that Claude was involved in the wording. It could not reliably distinguish between a fully generated text and one that had been extensively edited.
According to Google’s SynthID product description, the company watermarks, among other things, text generated by the Gemini app and its web interface. One detail makes the difference here: on the same page, Google describes the SynthID Detector as a testing portal for selected media professionals, where image, video or audio files can be uploaded. This does not mean that all users have been able to check arbitrary text passages there for free since May 2025. A live test with Gemini produces the following response: “For plain text, there is currently no reliable method or universally applicable marker (such as an invisible watermark) that allows end users to conclusively determine who authored the text.”
The situation is similar with ChatGPT. OpenAI has investigated various ways of identifying AI-generated text, including watermarks and methods for detecting linguistic patterns. The company also describes the difficulties involved: even a translation or thorough rephrasing can weaken a watermark. OpenAI currently does not offer a reliable public verification tool for ChatGPT-generated texts. If you paste a text into ChatGPT and ask, “Was this text AI-generated?”, you may receive a somewhat more detailed answer, but the basic message remains the same: “No, this cannot be reliably determined from the text alone. It could have been written by either a human or an AI.”
With images, the situation is different. While the origin of a text cannot reliably be inferred from its writing style, images can contain technical provenance information. Instead of merely examining whether an image looks typically AI-generated, it is sometimes possible to technically verify whether it has been marked as AI-generated or AI-edited.
What C2PA Proves About Images – and What It Doesn’t
C2PA, frequently mentioned in connection with Content Credentials, can be understood in simplified terms as a digital record of origin. A provider can attach signed information to an image file, indicating, for example, that it was created or edited using a particular tool. This is an important distinction from conventional AI detectors: they merely estimate whether content probably originated from AI based on certain characteristics. If valid C2PA information is found, however, it is possible to verify who issued it and whether it has subsequently been altered.
However, this does not prove that the image itself shows the truth. C2PA can document how a file was created or edited, but not whether the depicted scene actually took place. Missing Content Credentials are not proof that an image is authentic. Even a screenshot can remove the original provenance information. For example, if I open an image generated with ChatGPT on my iPhone and take a screenshot, a new file is created that generally no longer contains the original C2PA information.
This is precisely why providers such as OpenAI and Google also use invisible watermarks embedded in the image itself. A screenshot may therefore remove the C2PA record, but not necessarily every trace of AI origin. Google DeepMind has specifically tested SynthID for its robustness against modifications such as compression, resizing and cropping. OpenAI also describes SynthID as an additional layer of protection because the signal can survive modifications such as screenshots, where C2PA information is lost.
A simple screenshot is therefore not necessarily enough to conceal the origin of an AI-generated image. With more extensive modifications, however, the signal may also be weakened to the point where it can no longer be reliably detected. Ultimately, the conclusion remains somewhat unsatisfying: the presence of provenance information can tell us something, while its absence tells us surprisingly little. To paraphrase Socrates: above all, we know what we do not know. And if the technical evidence already has its limitations with images, the question of how reliably AI can be detected becomes even more pressing when there is no image file to examine, only text.
How Well Does Detection Work Outside a Demo?
The amount of text plays a decisive role in detection. Anthropic identifies short texts, highly factual passages and simple corrections as particularly difficult cases. The reason is simple: the fewer linguistic decisions a model can make, the harder it becomes to embed a statistically detectable signal in the text. A longer, freely formulated response offers considerably more opportunities. However, no fixed threshold can be derived from this. Statements such as “AI watermarks only work above 200 tokens” turn the results of individual experiments into a general rule that does not actually exist. Whether a signal can be detected depends not only on length but also on the type of text being examined and the method used.
And even a watermark that is initially easy to detect does not necessarily remain detectable forever. What matters, therefore, is what happens to the text after generation. Kirchenbauer and colleagues were able to detect statistical traces under certain conditions even after human or machine paraphrasing, provided sufficient text was available. Another study by Cheng and colleagues on SIRA reached a very different conclusion for targeted rewriting: it was able to evade seven examined methods in almost every case under the respective test conditions.
This is not a contradiction but demonstrates how strongly the results depend on the method, the amount of text and the type of editing. Research therefore supports neither the simple rule that “paraphrasing removes every watermark” nor the opposite. A watermark can survive editing. How much of it remains reliably detectable ultimately depends on the specific method and the specific text.
And How Reliable Are Conventional AI Detectors?
Watermarks are only one way of identifying AI-generated text. Most AI detectors currently available instead look for statistical and linguistic patterns in the finished text. There is no general answer to how reliably this works. However, some recent studies show that individual detectors can achieve surprisingly high detection rates under controlled conditions.
Van Vlasselaer, Van Droogenbroeck and Spruyt compared four products in 2026 using 160 academic documents of known origin: fully human-written, fully AI-generated, mixed and subsequently “humanized” papers. Pangram performed best on this dataset. For fully AI-generated papers, it achieved a detection rate of 97.5 percent under a more permissive classification criterion, but only 65 percent under the stricter measure. The other tools frequently underestimated the proportion of AI-generated content. All fully human-written texts in the sample were classified correctly.
These results demonstrate that individual detectors can indeed achieve high detection rates under certain conditions. However, they cannot automatically be generalized to other types of text. The study examined academic papers, not a representative sample of German blog articles, and the fully AI-generated subgroup was small.
The researchers themselves therefore recommend using detectors only as preliminary indicators and never as the sole basis for decisions with significant consequences. This leaves a fundamental problem: technical methods can provide indications of AI-generated content, but they cannot guarantee comprehensive detection. This makes the question of whether the origin of such content must at least be legally disclosed all the more important. And this is where the EU AI Act comes into play.
When Must AI-Generated Content Be Labeled?
If AI-generated content cannot always be reliably detected technically, the next question is obvious: must it at least be labeled? The EU now has specific rules addressing this issue. Since August 2, 2026, the transparency obligations under Article 50 of the EU AI Act have applied. However, the regulation does not contain a simple rule stating that “everything created with AI must be labeled.”
The first important distinction concerns who is responsible for labeling. The AI Act differentiates between providers of AI systems and those who use and publish AI-generated content.
For providers such as OpenAI, Anthropic or Google, Article 50(2) of the AI Act is relevant. Systems that generate synthetic text, images, audio or video must generally mark their outputs in a machine-readable format and make them detectable as artificially generated or manipulated. The solutions used should be robust, reliable and interoperable as far as technically feasible. The regulation does not prescribe a specific method. C2PA or watermarks such as SynthID are therefore possible technical solutions, but not the one solution mandated by law.
The European Commission has also developed a voluntary code of practice. Its purpose is to help companies implement these legal requirements in practice. It is the code of practice that is voluntary, not the transparency obligation itself.
For editorial teams, companies and other publishers, however, Article 50(4) is decisive. Anyone who publishes AI-generated or manipulated text for the purpose of informing the public about matters of public interest must generally disclose its artificial origin. However, the article contains an important exception: if the AI-generated content has undergone human review or editorial control and a natural or legal person assumes editorial responsibility, this disclosure obligation does not apply. And yes, that certainly leaves room for ambiguity.
So What Am I Actually Allowed to Do – and What Not?
For editorial teams, bloggers and other content creators, the most interesting rule is hidden in an exception. Not every text created with AI must be labeled as such. The disclosure obligation under Article 50(4) concerns published AI-generated or manipulated texts intended to inform the public about matters of public interest. According to the European Commission, this includes, for example, politics, public health, consumer safety, the environment, science, and economic or cultural developments that may be subjects of public debate.
And even such texts do not have to be labeled if they have undergone sufficient human review or editorial control and someone assumes editorial responsibility. The Commission has since clarified what this means: human review must address the actual content and be carried out by someone with the necessary knowledge and professional judgment. Editorial control means that a responsible person has the authority to review, modify or reject the text. This explicitly includes fact-checking and assessing the trustworthiness of sources.
For content creators, this results in an important distinction. Someone who asks ChatGPT to write an article, briefly polishes it and then publishes it cannot invoke the exception solely because of that editing. By contrast, someone who verifies the claims, checks the sources, makes substantive decisions, modifies the text where necessary and personally assumes responsibility for publication is much closer to what the Commission understands by human review and editorial control.
There is therefore still considerable room for interpretation. The AI Act does not provide content creators with a simple checklist for clearly determining when an AI-generated text must be labeled. Terms such as “matter of public interest,” “human review” and “editorial control” have been described in greater detail, but their boundaries remain open.
This quickly becomes relevant in content marketing. An article about a new running shoe collection would probably raise few concerns. But what about a guide to running shoes for people with knee problems? There is no fixed threshold at which a topic becomes a matter of public interest.
Human oversight remains similarly difficult to define. The Commission makes it clear that simple spelling or grammar corrections are not sufficient. However, it does not specify minimum requirements for how extensively a text must be modified, how many claims must be verified or what proportion may still come directly from AI. Between “ChatGPT writes, human clicks publish” and a fully researched and editorially responsible article lies a broad spectrum that cannot be reduced to a simple percentage rule.
For content creators, this is frustrating but important: there is no general labeling obligation for every AI-assisted text, and at the same time, there is no simple formula that conclusively establishes whether the exception for editorially controlled content applies.
Does a Watermark Affect Google Rankings?
In its guidance on generative AI, Google explains that using AI to create text is not in itself a violation of its Search policies. What can become problematic, however, is producing large numbers of automatically generated pages without additional value, particularly when their primary purpose is to manipulate rankings. The published policy therefore evaluates the purpose and quality of the result, rather than categorically judging the origin of every sentence. Google’s more detailed guidance on helpful content similarly emphasizes reliability, demonstrable expertise and usefulness to people.
This allows for a precise but limited conclusion: Google’s public documentation does not describe a blanket ranking penalty simply because a text contains a watermark or was created using AI. This does not mean that outsiders know every internal ranking signal or can rule out the possibility that provenance signals might be used in another context. Anyone claiming that Google “definitely never checks for SynthID or Claude signals” knows more than Google has publicly disclosed. For practical content strategy, however, the documented position is sufficient: a detector score is not a quality criterion that can replace editorial work under Google’s guidelines.
Would it help to run a text through several models until no signal can be measured anymore? That may weaken a particular watermark under certain circumstances, but it says nothing about quality and does not reliably predict how another detector will evaluate the text. Moreover, every additional pass takes time and can damage evidence, tone of voice and subject-specific nuances. For an article based on original research, this is a strange kind of optimization: investing effort into making its origin harder to detect while leaving the question of factual accuracy unresolved. Because one thing remains beyond dispute: editorial responsibility always lies with the publisher. Always.